Self-Hosting an AI-Native CRM in 2026
You can have Relaticle running with a working AI chat assistant and MCP server on your own infrastructure in under 20 minutes, using Docker and a text editor. This guide covers the three deploy paths Relaticle documents for self-hosting (Docker Compose, Coolify, and Dokploy), how to point the built-in assistant at a local Ollama model instead of a cloud API, and what's genuinely different about running the AI features yourself instead of on Relaticle's hosted plan.
Why the AI parts are worth self-hosting too
A lot of CRMs that advertise an AI assistant or an MCP integration still run those specific features from their own cloud, even when the rest of the product is source-available. Relaticle's AI stack is ordinary application code, not a hosted add-on: the chat assistant is a Laravel package, the MCP server is a route registered in routes/ai.php like any other, and neither is gated behind a subscription check when the billing feature flag is off, which it is by default in the published Docker image. You can point the assistant at Anthropic or OpenAI with your own API key, or skip cloud providers entirely and run a local model through Ollama; both paths use the same chat interface and the same CRM access underneath. Separately, the MCP server exposes its full tool surface (search and fetch, plus full create/read/update/delete on companies, people, opportunities, tasks, and notes) to any MCP client, self-hosted exactly as it runs on Relaticle's own cloud plan; connecting Claude to it takes about two minutes. Relaticle itself ships under AGPL-3.0.
Requirements
All three deploy paths below pull the same official Docker image and the same compose.yml; they mostly differ in how much infrastructure you already have running.
| Deploy option | What you need | Approx. time |
|---|---|---|
| Docker Compose (your own server) | 2 GB RAM minimum (4 GB recommended), Docker 20.10+, Docker Compose v2+ | ~15 minutes |
| Coolify | A running Coolify instance, a domain to point at it | ~15 minutes |
| Dokploy | A running Dokploy instance, a domain to point at it | ~15 minutes |
| Manual, no containers | PHP 8.5+, PostgreSQL 17+, Redis 7+, Node 20+, Composer 2+, Nginx or Apache, Supervisor | ~45-60 minutes |
Deploy with Docker Compose
This is the path Relaticle's own guide leads with, and it's the fastest if you already have a server with Docker on it.
Download the compose file:
curl -o compose.yml https://raw.githubusercontent.com/Relaticle/relaticle/main/compose.yml
Generate an application key:
echo "APP_KEY=base64:$(openssl rand -base64 32)"
Create a .env file next to compose.yml with at least the required variables:
APP_KEY=base64:your-generated-key-here
DB_PASSWORD=your-secure-database-password
APP_URL=https://crm.example.com
Start everything:
docker compose up -d
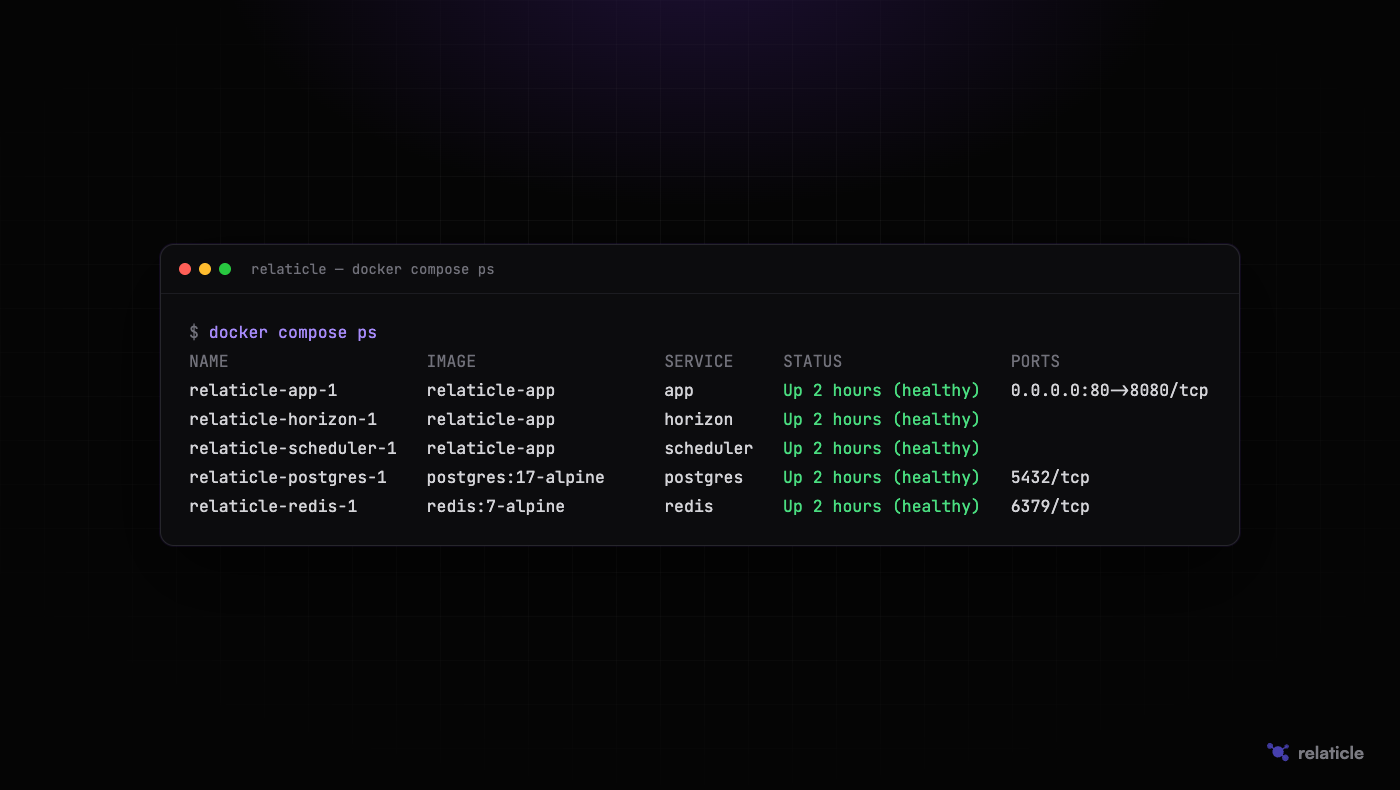
This brings up five containers: the app (nginx + PHP-FPM), a Horizon worker for queued jobs, a scheduler container running schedule:work, PostgreSQL 17, and Redis 7. Database migrations run automatically on first boot, so there's no separate migrate step.
Create your first admin user:
docker compose exec app php artisan make:filament-user
Pick the app panel when prompted, and your CRM is live at {APP_URL}/app. If you also want the instance-wide sysadmin panel (useful later, see the limitations section below), run docker compose exec app php artisan sysadmin:create instead, or choose sysadmin at the same prompt.
Put a reverse proxy in front for TLS. The self-hosting guide includes ready-to-use Nginx, Caddy, and Traefik configs; Caddy is the least fuss since it provisions Let's Encrypt certificates automatically. Whatever you use, the app trusts X-Forwarded-* headers from private-network and loopback ranges (which covers Coolify, Dokploy, and Traefik on a Docker network) and rejects them from public IPs, so proxy headers can't be spoofed from outside.
Deploy with Coolify
If you're already running Coolify for other projects, adding Relaticle takes about the same five minutes as any other Docker Compose resource:
- Create a new project in the Coolify dashboard.
- Add a resource, choose Docker Compose, select Empty as the source, and paste in the contents of
compose.yml. - Set the required environment variables (
APP_KEY,DB_PASSWORD,APP_URL) in the resource's Environment Variables tab. - Set your domain under the app service's Settings tab. Coolify provisions the SSL certificate automatically.
- Click Deploy, then open Coolify's Terminal feature for the
appcontainer and runphp artisan make:filament-user.
Deploy with Dokploy
Dokploy follows the same shape:
- Create a project, then add a Compose service with source set to Raw, pasting in
compose.yml. - Set
APP_KEY,DB_PASSWORD, andAPP_URLin the service's Environment tab. Also setAPP_PORT=8080, since Dokploy's own dashboard usually holds port 80, so mapping the app container to 8080 avoids a conflict. - Click Deploy and wait for health checks on all five containers to pass.
- Add your domain under the app service's Domains tab, set the container port to 8080, and enable HTTPS (Dokploy handles Let's Encrypt).
- Open Dokploy's terminal for the
appcontainer and runphp artisan make:filament-user.
Skipping containers entirely
If Docker isn't an option, Relaticle also documents a manual install: clone the repo, composer install --no-dev --optimize-autoloader, npm ci && npm run build, php artisan migrate --force, set permissions on storage and bootstrap/cache, then run Horizon under Supervisor and schedule:run from cron. It's the same application, just without the container boundary. That's worth it if you're already standardizing a fleet of bare-metal Laravel apps under one process manager, but there's no shortcut version, so budget closer to an hour and follow the full guide.
Wiring up the AI: Ollama and the MCP server
Once the containers are up, the AI assistant and the MCP server are both already running. They just need a model to talk to.
Local model through Ollama. Set two environment variables and restart:
OLLAMA_BASE_URL=http://host.docker.internal:11434
OLLAMA_MODEL=qwen3:14b
OLLAMA_BASE_URL defaults to http://localhost:11434, which from inside a container means the container itself, not your host. On Docker Desktop (Mac or Windows), host.docker.internal reaches the host out of the box. On a Linux server, which is where most self-hosted installs live, two more steps are needed: that hostname only resolves if you add it to the app and horizon services in your compose file,
extra_hosts:
  - "host.docker.internal:host-gateway"
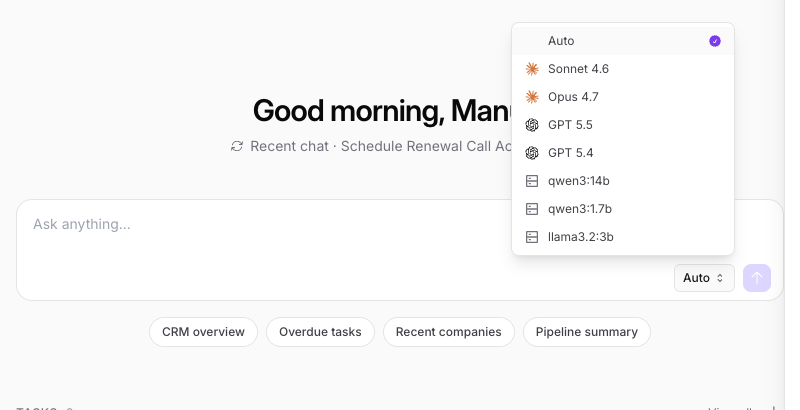
and Ollama itself binds to loopback by default, so set OLLAMA_HOST=0.0.0.0 (per the Ollama FAQ) before it will accept a connection from inside a container. Alternatively, run Ollama as another compose service on the same network and point OLLAMA_BASE_URL at its service name. Setting OLLAMA_MODEL adds that tag to the in-app model picker.
Not every local model is worth trusting with write access. The assistant calls the same 37 CRM tools (as of August 2026) the MCP server exposes to search, create, update, and delete records, and small models frequently claim an action succeeded without actually invoking the tool. Before pointing real data at a model, verify it with:
docker compose exec app php artisan chat:models --probe=ollama
This runs a live tool-calling smoke test against your Ollama endpoint. qwen3 and llama3.1:70b-class models are reasonable starting points; a GPU makes the difference between usable and painfully slow for anything in that range. If you'd rather serve multiple models to multiple users at once, SELF_HOSTED_AI_URL, SELF_HOSTED_AI_KEY, and SELF_HOSTED_AI_MODELS point the same picker at any OpenAI-compatible server (vLLM, LM Studio, LocalAI).
MCP server. With no MCP_DOMAIN set, the server is reachable at {APP_URL}/mcp out of the box, no separate deploy step. Create a personal access token from Settings → Access Tokens in the app, then point any MCP client at it:
{
  "mcpServers": {
    "relaticle": {
      "type": "streamable-http",
      "url": "https://crm.example.com/mcp",
      "headers": { "Authorization": "Bearer YOUR_TOKEN" }
    }
  }
}
That's the full tool surface: account info, cross-entity search/fetch, and CRUD across companies, people, opportunities, tasks, and notes, plus schema resources so the client can see your custom fields. Nothing about the route is different on a self-hosted install versus the hosted one, other than the domain you point at.
What you actually give up self-hosting
Self-hosting the AI features doesn't mean unlimited or unmetered usage, and it's worth knowing where the edges are before you rely on it.
-
Chat is still credit-metered, even with your own API key or a local model. Every team, self-hosted or not, starts on the Free plan: 300 credits per calendar month, resetting automatically. Running Ollama on your own GPU doesn't change that ceiling by itself, since it's enforced in the same code path regardless of which model answered. If a team needs more, the instance-wide
sysadminpanel ({APP_URL}/sysadmin, from the account you created earlier) can adjust a team's balance or switch its plan directly, with no Stripe account required for that path.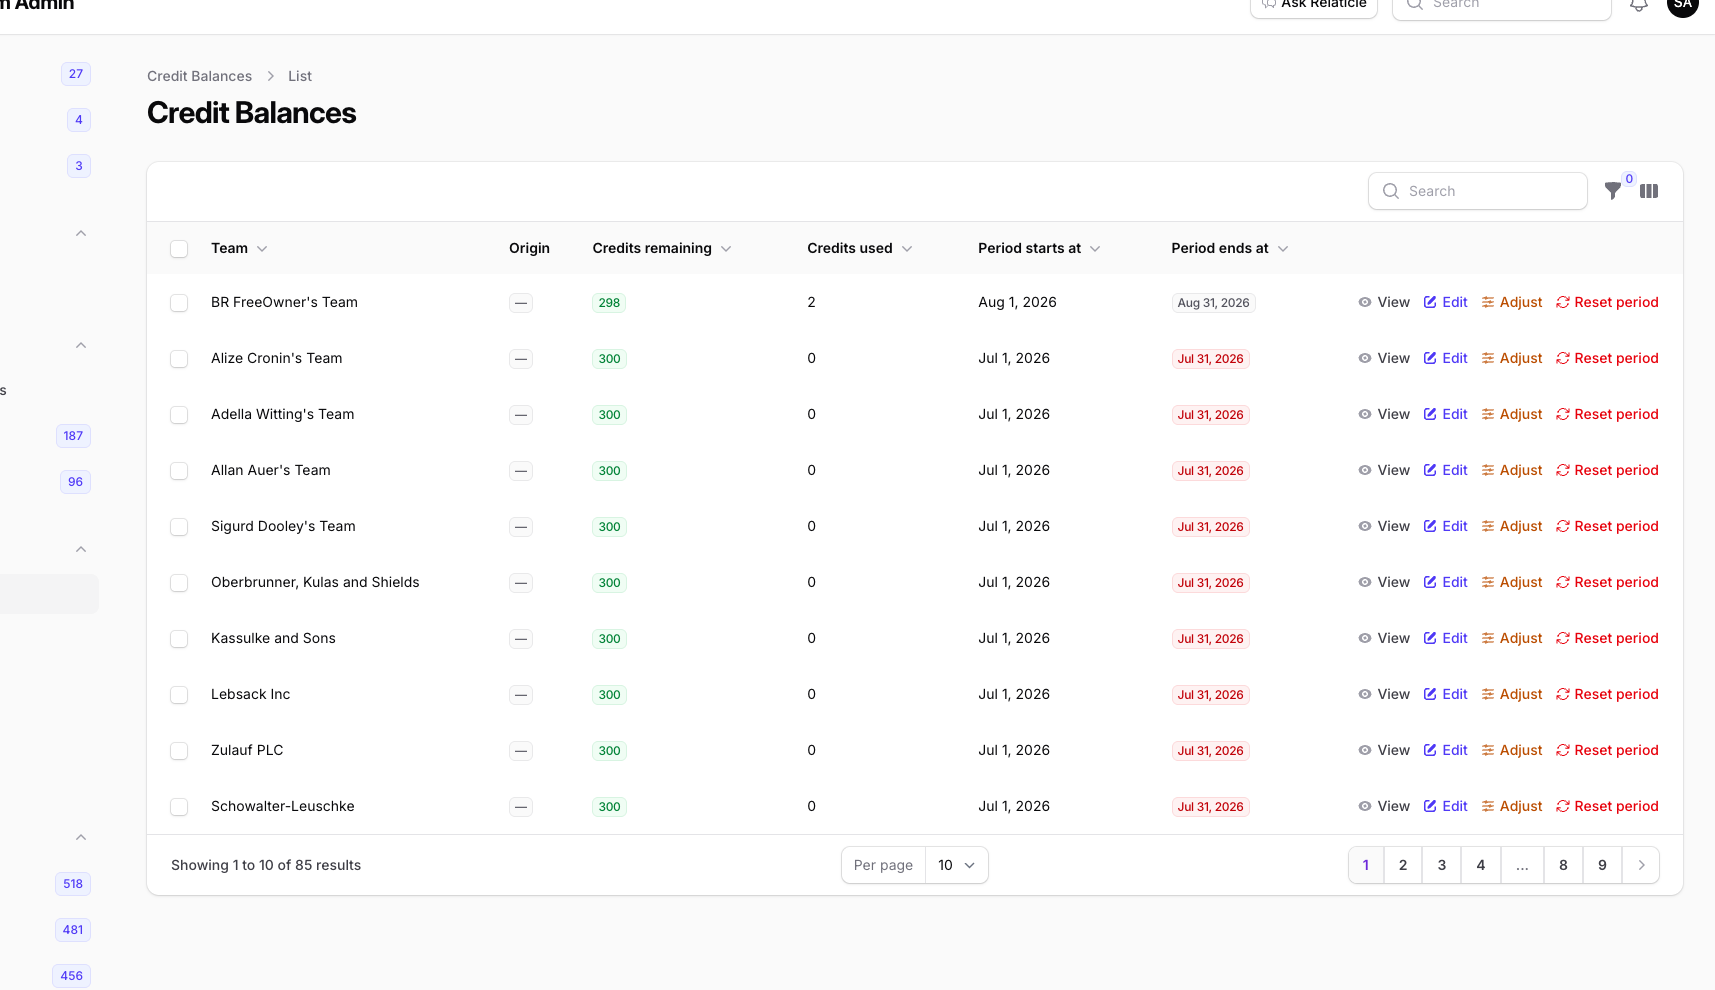
-
Every response has a 120-second budget. If a model doesn't finish in time, the turn stops cleanly (your message stays in the conversation with a clear notice, nothing is silently lost), but "thinking" models like
qwen3reason before answering and hit that ceiling more often. A smaller or faster model, or a GPU, helps. -
The one-write-at-a-time guarantee is weaker for self-hosted models. Cloud providers enforce it at the API level; self-hosted models rely on prompt instructions instead, since there's no equivalent API switch. You still have to approve every write before it's saved. It's just a softer guarantee under the hood.
-
Tool-calling reliability varies a lot by model. This is the reason
chat:models --probeexists: run it before trusting any new local or self-hosted model with real writes, rather than finding out the hard way that a smaller model silently skipped a delete it claimed to have made.
None of this is specific to being self-hosted versus using Relaticle's cloud plan. It's how the assistant behaves everywhere. The only self-hosting-specific piece is that there's no billing UI to hit a paywall against, so you either raise the ceiling from the sysadmin panel or wait for the monthly reset.
Where to go from here
Full environment variable reference, upgrade steps, backup and restore commands, and troubleshooting for restart loops and failed migrations are in the self-hosting guide: relaticle.com/developers/self-hosting. For the complete MCP tool list, schema resources, and setup instructions for Claude Desktop, Claude Code, Cursor, and VS Code, see relaticle.com/developers/mcp.
Related posts
Let Claude Code Run Your Sales Pipeline
Five real Claude Code sessions against Relaticle's MCP server: pipeline review, data entry, task cleanup, custom fields, and a delete it wouldn't rush.
What 'Agent-Native CRM' Actually Means
Agent-native CRM is a checklist, not a marketing label: full write access, approvals for chat, self-host parity, markdown for agents, first-party tooling.
How to Connect Claude to Your CRM with MCP
Connect Claude to Relaticle via MCP in minutes: OAuth setup, all 37 tools explained, and why MCP writes commit directly with no approval gate.