Backups, upgrades, and security for a self-hosted CRM
Running your own CRM means owning its operational risks as well as its data. The practical answer is straightforward: back up PostgreSQL, uploaded files, and deployment secrets. Prove that you can restore them. Back up before upgrades and configure the security basics before relying on the instance. The procedure below passed a restore drill on Relaticle's Docker Compose deployment. Apply it to your own configuration before relying on the result.
This is not an argument that self-hosting is free of work. It is an argument for doing the work deliberately. A CRM holds the record of customer relationships and business activity. If the database disappears, or an upgrade leaves it in a state you cannot unwind, the application containers are not the hard part. The data is.
Relaticle uses PostgreSQL, Redis, and a Horizon queue worker, and it can deploy on a single server. Its documented Docker Compose path also supports Dokploy and Coolify. That makes the operating surface manageable, but it does not remove the need for an operating routine. For deployment detail, use the full self-hosting guide. For the costs and tradeoffs around running your own system, we covered the money side separately.
Take a consistent backup before changing the deployment
Back up PostgreSQL, uploaded files, deployment configuration, and the original APP_KEY. Encrypted custom fields need that key after recovery.
Use a short maintenance window so database records and uploaded files represent the same application state. Pause inbound integrations and let queued writes finish first.
These commands assume the default PostgreSQL database and user are both relaticle. Adapt both names if your deployment uses different values.
PostgreSQL documents pg_dump for database backups. The storage copy uses docker compose cp.
Run these commands from the directory containing your Compose file and .env:
set -e
umask 077
recovery_backup="backup-$(date +%Y%m%d-%H%M%S)"
mkdir "$recovery_backup"
docker compose stop app horizon scheduler
docker compose exec -T postgres pg_dump -U relaticle relaticle > "$recovery_backup/database.sql"
docker compose cp app:/var/www/html/storage/app "$recovery_backup/storage"
docker compose images > "$recovery_backup/images.txt"
docker compose up -d
If any backup command fails, investigate before upgrading. Confirm the application and workers recover when you restart them.
Record the exact application image digest alongside the backup. Keep recoverable deployment configuration and secrets in a protected recovery store.
Copy the database and storage backups to protected storage outside the application server. A backup beside the live data cannot survive losing that server.
The default Compose file does not schedule backups. Automate this procedure through your platform or scheduler, including failure alerts and retention.
Restore into a fresh, isolated deployment
Restore the same application image first. An upgrade and a recovery should be separate operations.
Prepare a new directory with the saved Compose configuration and original secrets. Use an isolated recovery host with outbound integrations blocked.
Set APP_URL to the recovery URL and bind APP_PORT to loopback, such as 127.0.0.1:8081. Clear APP_PANEL_DOMAIN and SYSADMIN_DOMAIN.
Set MAIL_MAILER=log in the recovery configuration. Do not copy production domains or reconnect live webhooks during the drill.
Pin the app, horizon, and scheduler images to the recorded image digest. Preserve the original APP_KEY and any separate encryption secrets.
Use a new Compose project name with empty volumes. Never point these commands at your running deployment.
Place the backup's database.sql and storage directory inside this new directory, then run:
set -e
export COMPOSE_PROJECT_NAME="relaticle-restore-$(date +%Y%m%d%H%M%S)"
docker compose up -d --wait postgres redis
docker compose create app
docker compose exec -T postgres psql -v ON_ERROR_STOP=1 -U relaticle relaticle < database.sql
docker compose cp ./storage/. app:/var/www/html/storage/app
docker compose run --rm --no-deps --user root -e AUTORUN_ENABLED=false app chown -R www-data:www-data /var/www/html/storage/app
docker compose up -d --wait app
docker compose ps
The database must be empty before import. Starting the application first runs migrations and creates tables that conflict with the dump.
The ON_ERROR_STOP setting makes psql fail on the first SQL error when set to 1. Without it, the command can finish successfully after reporting failed statements.
Do not replay old Redis queues into the restored instance automatically. Reconcile pending integrations and jobs before allowing new writes.
Sign in and verify record IDs, company-contact links, opportunities, notes, encrypted fields, and uploaded files. Compare attachment checksums with the originals.
Keep Horizon and the scheduler stopped throughout the recovery drill. Start them only at planned cutover after reviewing outbound configuration and pending jobs.
Verify both workers before returning the recovered deployment to service. Container health alone does not prove that your records and files survived.
Run this drill regularly and before relying on a changed backup process. Record the exact image, results, recovery time, and unresolved failures.
Tested September 24, 2026, with Relaticle 3.5.11, PostgreSQL 17, and Redis 7. A clean deployment and destructive restore passed nine data checks.
The restored CRM rendered the contact, linked company, and decrypted field in the browser. The restored attachment returned HTTP 200 with matching bytes.
Upgrade in the order that preserves a way back
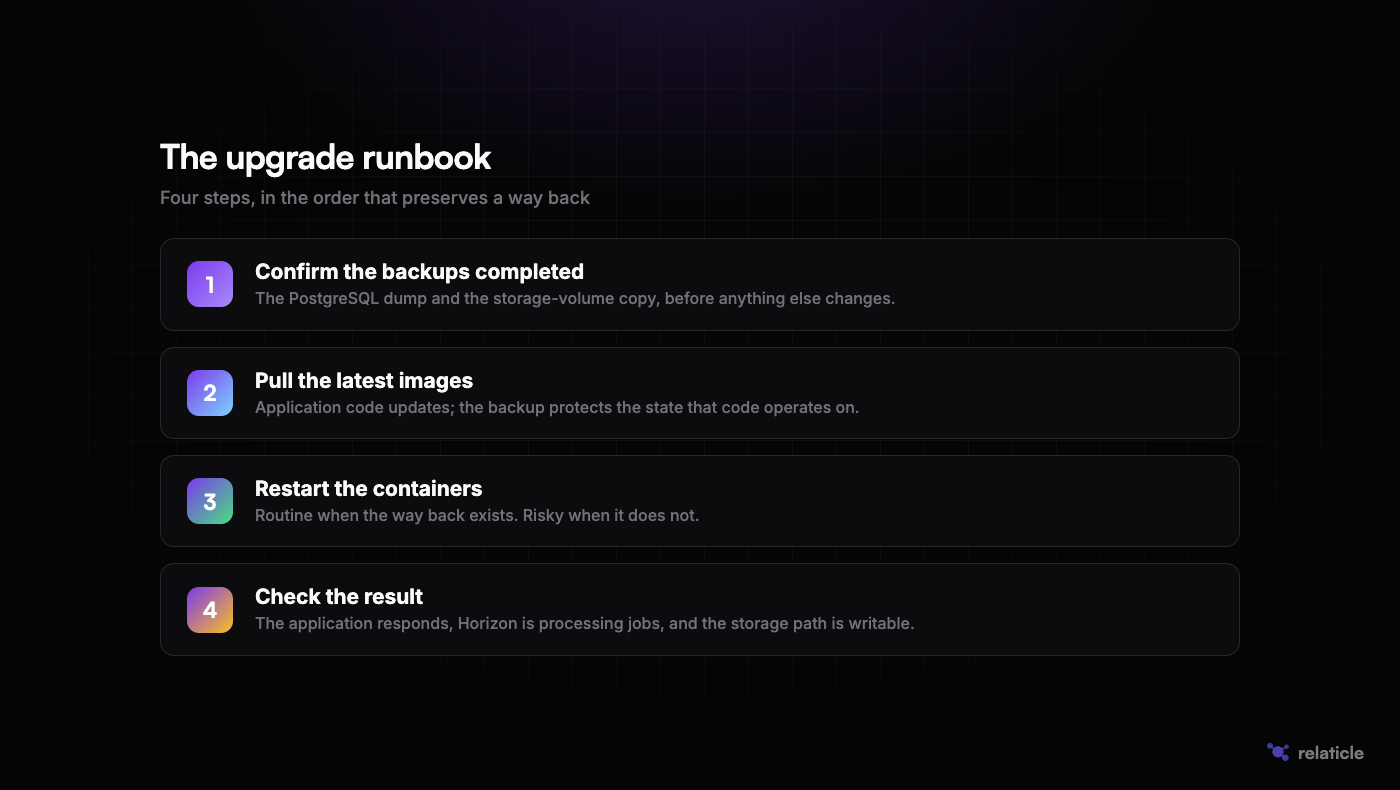
Back up first, pull the intended release images, then restart the containers. Pin the release so each application service runs the version you tested.
Back up first because an upgrade can include a database migration. If that migration changes the database in a way you cannot roll back, the pre-upgrade dump is the route back to the prior data state. Pulling images first does not preserve that route. Restarting containers first does not preserve it either.
This is the useful distinction between a routine update and a reversible update. Pulling the intended release images and restarting the containers updates application code. The backup protects the state that code operates on. Do not collapse those jobs into a single vague instruction to "deploy."
Use a short runbook for each upgrade:
- Confirm that the PostgreSQL backup and storage-volume backup have completed.
- Record the running image version, then pull the intended release images.
- Restart the containers.
- Check the application, queue worker, and uploaded files after deployment.
- If chat is configured, test its broadcasting connection and a complete send-and-approval flow.
On September 24, 2026, we upgraded a populated test deployment from Relaticle 3.5.9 to 3.5.11. All 12 migrations completed and all five services became healthy.
Record IDs, relationships, encrypted fields, and attachment bytes survived. This exercise covered the core application; AI inference and broadcasting need separate checks.
The final check is part of the upgrade, not an optional follow-up. A deployment can finish while a queue worker is not processing jobs or storage permissions prevent the application from writing files. Relaticle's troubleshooting guidance covers both classes of problem.
The goal is not to make upgrades feel risky. The goal is to make the risk explicit and bounded. You should know what you will restore before you change a running CRM. The documented path exists to keep the normal case simple, while preserving an answer for the non-normal case.
Set a security floor before adding extras
The security floor for this deployment is clear. Put TLS in front of the application through a reverse proxy. Keep APP_KEY and .env secrets out of Git. Do not expose the database to the public internet. Keep images current.
Relaticle documents Nginx, Caddy, and Traefik as reverse-proxy options for TLS. The important decision is not a preferred proxy. It is ensuring that traffic reaches the CRM through TLS and that the proxy is part of the documented deployment setup.
Treat APP_KEY and the rest of the .env file as secrets. They belong in the running environment, not in the repository. An accidental commit is not a deployment shortcut. It is a secret-management failure that can persist in version history.
The database should remain off the public internet. The application needs PostgreSQL. The public internet does not need direct PostgreSQL access. Keeping the database private narrows the exposed surface without requiring a complicated architecture.
Keeping images current belongs in the same floor. It links directly to the upgrade routine: take backups, pull the intended release images, restart, and check the running system. Avoid treating a completed initial install as a finished security task.
Some practices sit outside this documented floor. SSH keys only and fail2ban are examples of general server hygiene. They can be sensible measures for a server, but they are not a substitute for the application-specific basics above. Start with the documented proxy, secrets, database exposure, and image-update practices. Add broader server hygiene according to the environment you operate.
Know the failure modes before you meet them
The self-hosting guide covers several honest failure modes. They are not reasons to avoid self-hosting. They are reasons to keep the guide and your runbook close to the deployment.
| Failure mode | Class of cause the guide covers |
|---|---|
APP_KEY missing on startup |
Required application configuration is missing at startup |
| Container restart loops | A container cannot stay up and needs deployment troubleshooting |
| 500s after deployment | The deployed application needs troubleshooting after the change |
| Horizon not processing jobs | The queue worker is not processing work |
| Permission errors on storage | The application cannot use the storage path as expected |
Each of these is easier to handle when you have a recent backup, a known upgrade order, and a clear view of what should be running. This is why operational discipline compounds. The same checks that make an upgrade safer also make a failure easier to diagnose.
We do not think self-hosting should pretend to be hands-off. You own the infrastructure and the operating routine. In return, Relaticle supports the built-in chat assistant and MCP server on self-hosted deployments. Chat needs its own model and broadcasting configuration; the base Compose file does not supply a complete chat deployment. That makes careful operations more important, not less.
Make the routine boring
The right outcome is a boring one. Backups run on schedule. A monthly restore drill proves they work. Upgrades start with a backup, then pull the intended release images and restart containers. TLS, secrets, private database access, and current images stay in place. The troubleshooting guide is part of the runbook, not a page you discover after an outage.
Use the procedure above for backup and recovery. The Relaticle self-hosting guide covers deployment, TLS, and troubleshooting. If you want the broader deployment context first, read how to self-host an AI-native CRM. Then make the restore drill real. That is the point at which a self-hosted CRM becomes an operated system rather than a container stack you hope will keep running.
Related posts
CRM data import checklist: CSV mapping and sample files
A CRM data import checklist with sample company and people CSV files, exact mappings, relationship checks, and a second-run update test.
CRM permissions for AI agents: an access checklist
Set CRM permissions for AI agents with a filled access worksheet, clear approval boundaries, and tests for denied writes and revoked connections.
HubSpot migration checklist: moving to another CRM
This HubSpot migration checklist covers moving to another CRM, including exports, associations, workflow replacements, and a worked cutover check.